MIVCN
案例介绍
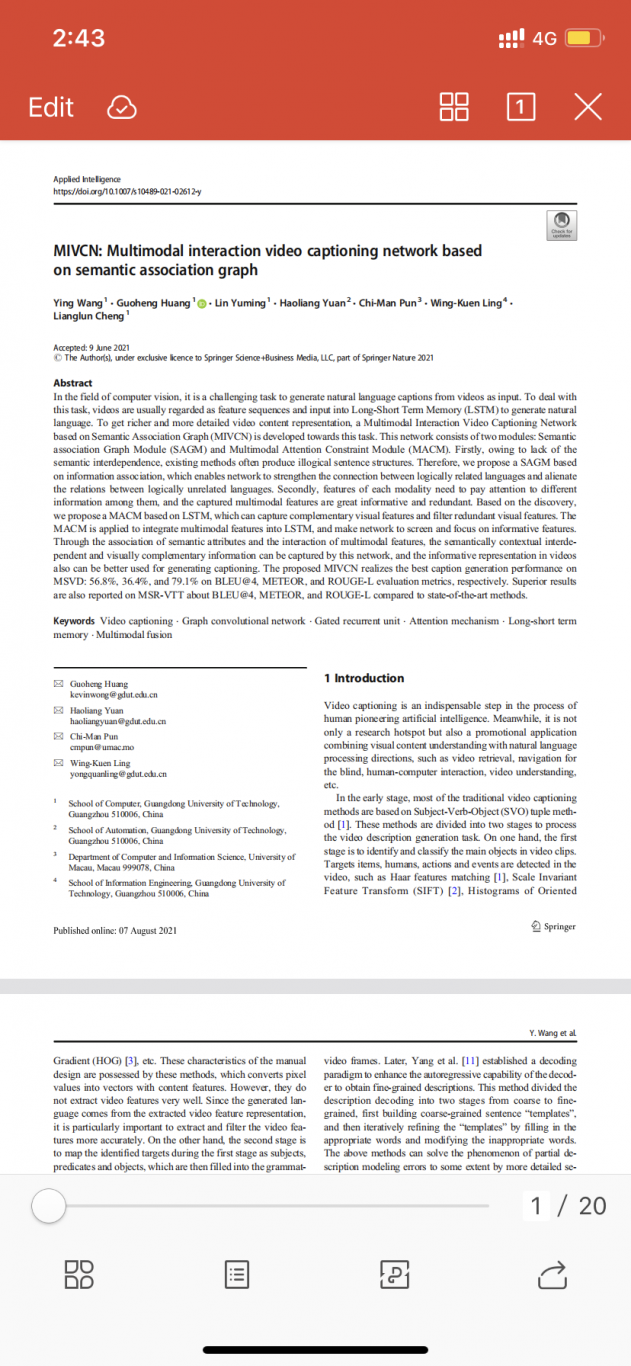
based on Semantic Association Graph (MIVCN) is developed towards this task. This network consists of two modules: Semantic association Graph Module (SAGM) and Multimodal Attention Constraint Module (MACM).
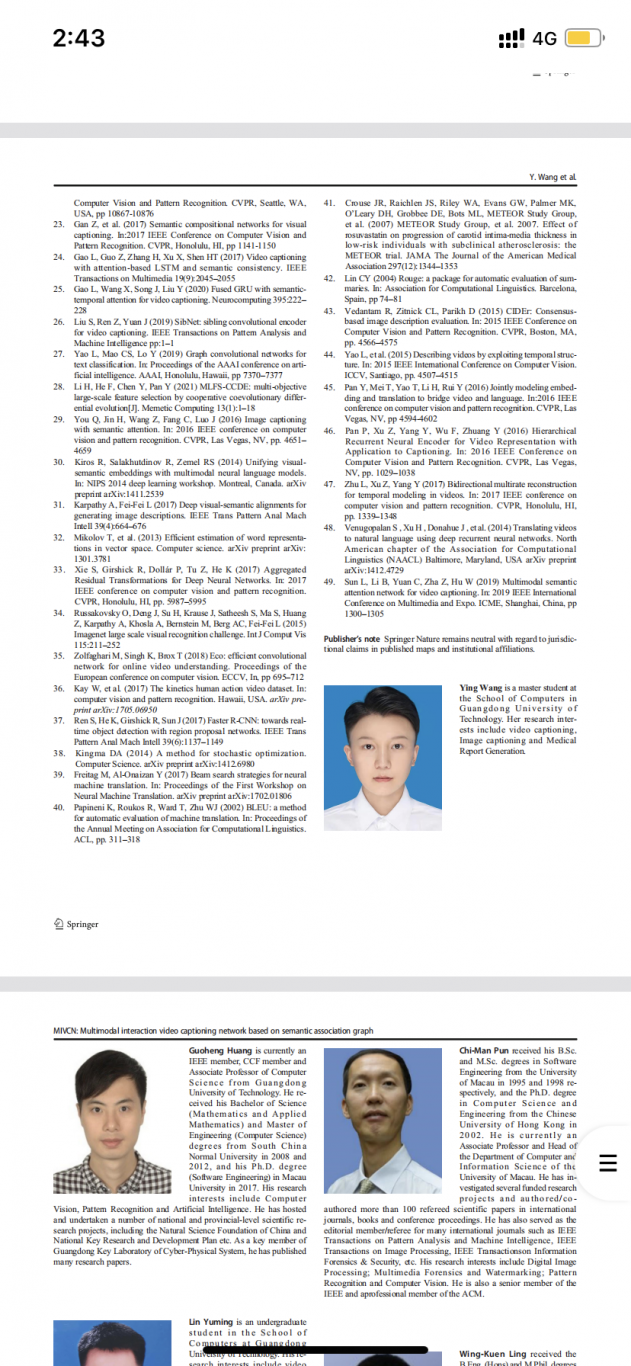
The proposed MIVCN realizes the best caption generation performance on MSVD: 56.8%, 36.4%, and 79.1% on BLEU@4, METEOR, and ROUGE-L evaluation metrics, respectively. Superior results are also reported on MSR-VTT about BLEU@4, METEOR, and ROUGE-L compared to state-of-the-art methods.
MIVCN

案例介绍
In the field of computer vision, it is a challenging task to generate natural language captions from videos as input. To deal with this task, videos are usually regarded as feature sequences and input into Long-Short Term Memory (LSTM) to generate natural language. To get richer and more detailed video content representation, a Multimodal Interaction Video Captioning Network
based on Semantic Association Graph (MIVCN) is developed towards this task. This network consists of two modules: Semantic association Graph Module (SAGM) and Multimodal Attention Constraint Module (MACM).
The proposed MIVCN realizes the best caption generation performance on MSVD: 56.8%, 36.4%, and 79.1% on BLEU@4, METEOR, and ROUGE-L evaluation metrics, respectively. Superior results are also reported on MSR-VTT about BLEU@4, METEOR, and ROUGE-L compared to state-of-the-art methods.
案例图片

相似案例推荐
-
中心医院新城分苑管理系统
项目概述 1. 目标 - 基于Vue+Eleme
-
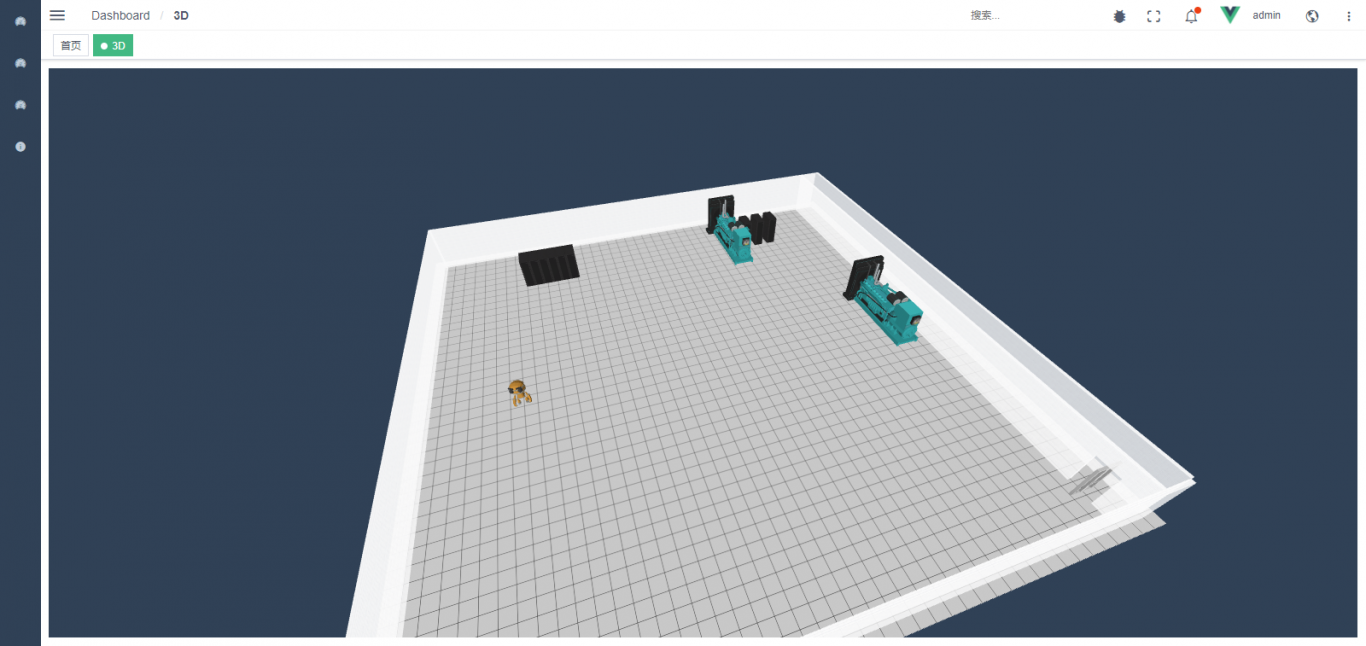
个人作品
主要是给客户呈现简单的3D化场景,根据不同的布局文件呈现不同
-
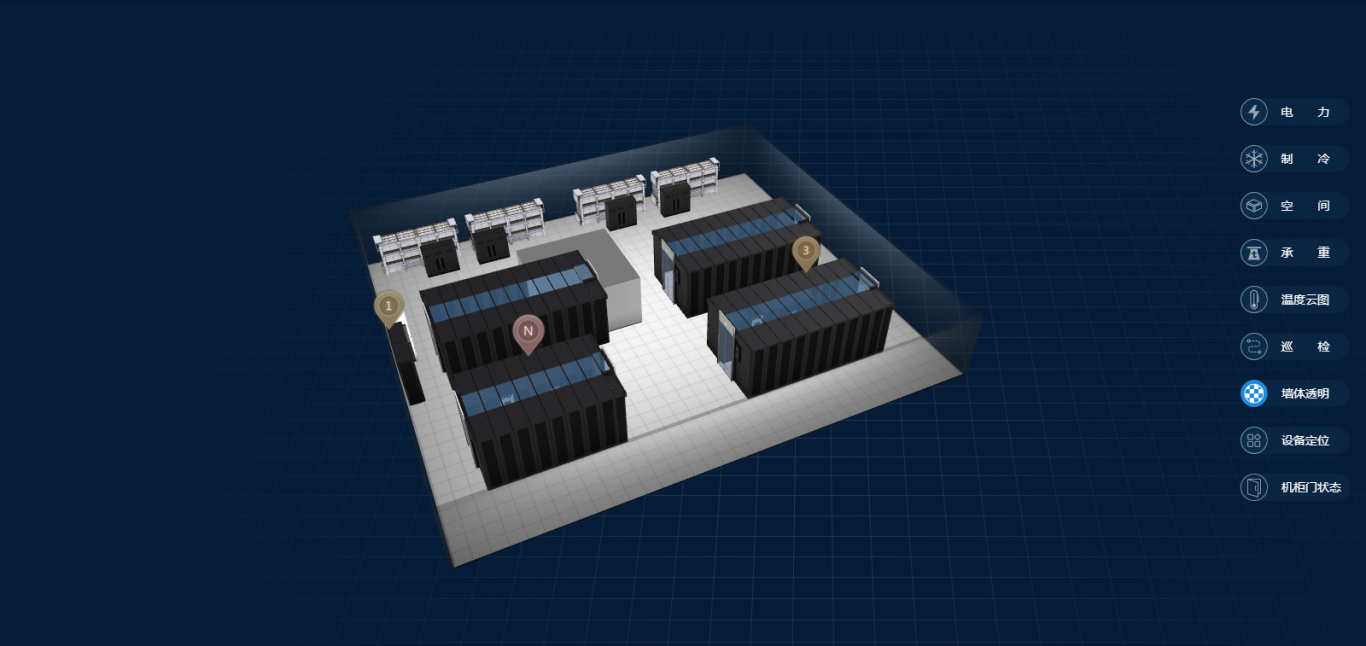
华为netEco
1 :华为3D机房 是一款嵌入在华为NetEco系统中一款可
-
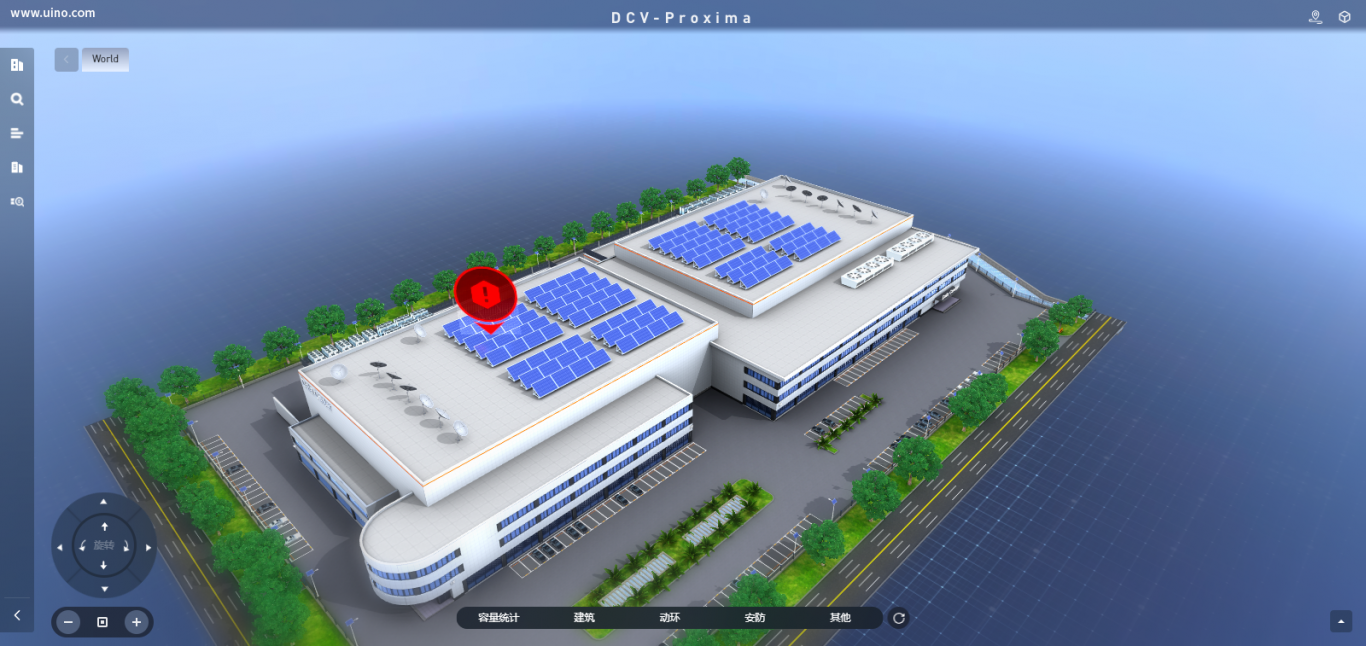
Dcv-Proxima
Dcv-Proxima 是公司数据中心可视化的核心产品,主要
-
网络爬虫
负责根据需要爬取的数据进行需求分析,分析目标网站的网站结构和
-
网络爬虫工程师
负责根据需要爬取的数据进行需求分析,分析目标网站的网站结构和
1小时精推人才
需求方专属客服,免费梳理匹配

